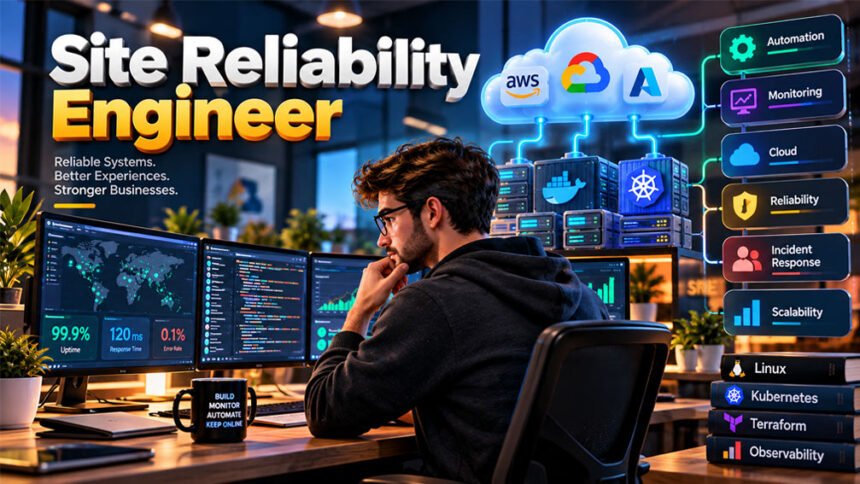
A Site Reliability Engineer (SRE) helps keep websites, apps, and software systems working properly. They help make systems fast, stable, and available to users.
SRE combines software development with IT operations. This guide explains what an SRE is, how SRE works, important skills and tools, benefits, challenges, and best practices.
What Is a Site Reliability Engineer?
A Site Reliability Engineer is a person who helps keep software systems working correctly. They use both coding and IT operations skills.
The main goal is to keep websites and applications reliable while developers continue adding new features and updates.
SRE is especially useful for large and complex systems. Managing these systems by hand can take a lot of time. It can also cause mistakes. SRE teams use automation to make this work easier.
Reliability is not only about keeping a website online. A website should also be fast and work correctly.
For example, a website may be online but take 20 seconds to load. Users may still see it as unreliable.
The SRE role can be different at each company. Large companies may have full SRE teams. Smaller businesses may have developers, cloud engineers, or DevOps engineers doing similar work.
History and Background of Site Reliability Engineering
Site Reliability Engineering is closely connected to Google.
Google developed the SRE approach to manage its large and complex online systems. These systems became difficult to manage with manual work alone.
Ben Treynor Sloss played an important role in developing SRE at Google.
One main idea behind SRE is simple: use software engineering to solve IT operations problems.
Modern applications may use many servers, databases, containers, cloud services, and data centers. They may also receive many software updates and sudden increases in traffic.
Managing all of this manually can be difficult. SRE uses automation, monitoring, software, and clear measurements to make the work easier.
SRE also has some similarities with IT Service Management (ITSM). However, they are different. ITSM covers the wider management of IT services. SRE focuses more on reliability, automation, performance, and production systems.
How Site Reliability Engineering Works
SRE starts by understanding what users expect from a service.
For example, users may expect a website to stay online, load quickly, and complete their requests without errors.
The SRE team measures these areas and creates reliability goals.
Monitoring tools collect information about the system. They can track errors, traffic, server health, response time, and resource use.
SREs study this information to find problems.
They also automate repeated work such as software deployment, system setup, configuration, and scaling.
When a system fails, the SRE team works to restore it. After the problem is fixed, the team checks what caused it and how to prevent it from happening again.
SRE is an ongoing process of monitoring, fixing, automating, and improving systems.
SLI, SLO, SLA, and Error Budgets
SLI, SLO, SLA, and error budget are common terms in SRE.
Service Level Indicator (SLI)
A Service Level Indicator (SLI) measures how well a service is working.
For example, an SLI may measure website availability, loading speed, errors, or successful requests.
Service Level Objective (SLO)
A Service Level Objective (SLO) is a reliability goal.
For example, a company may want 99.9% of requests to work correctly during a certain period.
An SLO gives the team a clear target.
Service Level Agreement (SLA)
A Service Level Agreement (SLA) is an agreement between a service provider and its customer.
It explains the level of service the customer should receive. There may also be consequences if the company does not meet the agreed level.
Error Budget
An error budget shows how much failure is allowed while still meeting an SLO.
For example, if the target is 99.9% availability, the remaining 0.1% is the allowed downtime for that period.
Error budgets help teams balance reliability with new software updates.
What Does a Site Reliability Engineer Do?
A Site Reliability Engineer works with both software and IT systems.
An SRE may manage cloud services, servers, databases, networks, and containers.
Monitoring is also an important part of the job. SREs use dashboards and alerts to check whether systems are working correctly.
They also automate repeated tasks. These can include software deployment, system setup, configuration, scaling, and maintenance.
SREs help when a production system has a problem. They find the cause, work with other engineers, and help restore the service.
Some SRE jobs include on-call work. This means an engineer must be available during certain times to handle serious problems.
SREs may also plan system capacity, improve deployments, write technical documents, and help developers build more reliable software.
The Role of Automation and Reducing Toil
Automation is an important part of SRE.
In SRE, toil means repeated manual work that takes time but does not create a long-term improvement.
For example, an engineer may need to restart the same service every few days. Restarting it fixes the problem for a short time, but the problem keeps coming back.
An SRE may find the real cause and fix it. They may also automate the restart if it is still needed.
Automation can help with deployments, system setup, configuration, monitoring, testing, scaling, and recovery.
Infrastructure as Code (IaC) also helps with automation. It lets engineers manage infrastructure using code or files instead of setting everything up by hand.
Common tools include Terraform, Ansible, Puppet, and Chef.
Automation should always be tested carefully. A bad automated action can quickly cause problems across many systems.
Monitoring and Observability
SRE teams need to know how their systems are working.
Monitoring checks known system conditions. For example, it can send an alert when a website has too many errors.
Observability helps engineers understand what is happening inside a system and why a problem happened.
Three common types of observability data are metrics, logs, and traces.
Metrics are numbers such as CPU use, memory use, errors, traffic, and response time.
Logs are records of events from applications, servers, and databases.
Traces show how a request moves through different services.
These types of information help SREs find and understand problems.
Teams should also avoid sending too many unnecessary alerts. Too many alerts can cause alert fatigue, where engineers become overwhelmed by notifications.
Incident Response and On-Call Work
Even a good system can sometimes fail.
A website may go offline, a database may become slow, or a software update may cause a problem.
SRE teams need a clear plan for these situations.
Monitoring tools can find a problem and send an alert to the engineer who is on call.
The engineer checks the problem and works to restore the service. Other teams may also help with serious incidents.
Runbooks provide instructions for handling common problems. They can explain what to check and what actions to take.
After a serious problem, the team may hold a post-incident review, also called a postmortem.
The team looks at what happened, why it happened, and how similar problems can be prevented.
SRE often uses blameless postmortems. The goal is to improve the system instead of blaming one person.
Safe Software Deployment and Change Management
New software updates can sometimes cause problems.
SRE teams use different methods to make software releases safer.
CI/CD can automate software building, testing, and deployment.
Automated testing can find many problems before an update reaches users.
A canary release sends only a small amount of traffic to a new software version first. If everything works correctly, more users can receive the update.
A blue-green deployment uses two versions or environments. Traffic can be moved between them when needed.
Feature flags allow teams to turn certain features on or off.
Teams should also have a rollback plan. This allows them to return to an older stable version if a new update causes problems.
Capacity Planning, Scalability, and Performance
A system needs enough resources to handle its users.
Capacity planning helps teams understand how many resources they need now and in the future.
SREs may monitor CPU, memory, storage, network traffic, databases, and user requests.
Past data can help teams understand when traffic may increase.
There are two common ways to increase system capacity.
Vertical scaling means adding more power to an existing machine.
Horizontal scaling means adding more machines to share the work.
Load balancers can spread traffic between different servers. Cloud services and Kubernetes can also automatically add resources when traffic increases.
Teams should balance performance and cost. Too few resources can cause slow services or outages. Too many unused resources can waste money.
Skills Required for a Site Reliability Engineer
An SRE needs several technical skills.
Common skills include programming, Linux, cloud computing, networking, databases, monitoring, automation, and troubleshooting.
Programming and Scripting
Coding is important for most SRE jobs.
SREs may use Python, Go, Java, JavaScript, C++, or other languages.
They use code to automate work, build tools, and solve system problems.
Shell scripting, Git, testing, and debugging skills are also useful.
Cloud Computing
Many SREs work with cloud services such as AWS, Microsoft Azure, and Google Cloud.
They may work with cloud servers, storage, databases, networks, monitoring, and security.
They should also understand cloud regions and availability zones.
Containers and Kubernetes
Containers package an application with the files and software it needs.
Docker is a popular container technology.
Kubernetes helps manage, deploy, and scale containers.
An SRE working with Kubernetes may need to understand networking, storage, scaling, backups, and system updates.
Infrastructure as Code
Infrastructure as Code lets engineers manage infrastructure using code or files.
Common tools include Terraform, CloudFormation, Ansible, Puppet, and Chef.
It can make infrastructure easier to create, repeat, review, and manage.
Networking
Networking is an important SRE skill.
SREs may need to understand TCP/IP, DNS, ports, routing, firewalls, load balancing, and CDNs.
This knowledge helps them find network problems that may affect applications.
Databases
SREs may work with PostgreSQL, MySQL, MongoDB, Cassandra, Redis, and other databases.
They should understand backups, recovery, performance, connections, replication, and scaling.
Backups should also be tested to make sure data can actually be restored.
Security
Security is important for system reliability.
SREs should understand access control, encryption, backups, network security, and secure system settings.
Passwords, API keys, and certificates should also be stored safely.
SREs may work with security teams when needed.
Communication and Collaboration
SREs often work with developers, IT teams, security teams, support teams, and managers.
They need to explain technical problems in a clear way.
Writing skills are also useful because SREs create runbooks, incident reports, guides, and other technical documents.
Common SRE Tools
SREs use many different tools. The exact tools depend on the company.
Common cloud platforms include AWS, Microsoft Azure, and Google Cloud.
Docker and Kubernetes help manage containers.
Terraform and CloudFormation help manage infrastructure. Ansible, Puppet, and Chef can automate system setup and configuration.
Monitoring tools include Prometheus, Grafana, Datadog, and New Relic.
CI/CD tools include Jenkins, GitHub Actions, and GitLab CI.
PagerDuty and similar tools can send important alerts to on-call engineers.
Git tracks changes to code and configuration.
HashiCorp Vault can help protect passwords, API keys, and other sensitive information.
An SRE does not need to know every tool. Understanding the main ideas behind SRE is more important.
Site Reliability Engineer vs DevOps
SRE and DevOps are related, but they are not the same.
DevOps helps development and operations teams work together. It focuses on teamwork, automation, and faster software delivery.
SRE focuses more on keeping systems reliable and measuring their reliability.
SRE teams may use SLIs, SLOs, error budgets, monitoring, automation, and incident reviews.
Both DevOps and SRE use many of the same tools and practices.
A company can use both SRE and DevOps together.
SRE vs Traditional IT Operations and ITSM
Traditional IT operations manage servers, networks, applications, and other IT systems.
IT Service Management (ITSM) covers the wider process of managing and supporting IT services.
SRE focuses more on keeping production systems reliable through engineering and automation.
Traditional IT operations may use more manual work. SRE tries to automate repeated tasks where possible.
SRE also uses SLIs, SLOs, and error budgets to measure reliability.
A company can use both ITSM and SRE. They do not have to replace each other.
Benefits of Site Reliability Engineering
SRE can help make software systems more reliable.
Good monitoring can help teams find problems earlier. Clear incident plans can help teams restore services faster.
Automation can reduce repeated manual work and some human mistakes.
SRE can also make software updates safer. Testing, canary releases, feature flags, and rollback plans can reduce problems caused by new releases.
Capacity planning and automatic scaling can help systems handle more traffic.
Observability can help teams understand how their systems are working.
SRE can also improve teamwork between developers and operations teams.
For users, this can mean faster, more stable, and more reliable services.
Challenges and Drawbacks of SRE
SRE also has some challenges.
SREs need many technical skills. Experienced SREs can therefore be difficult and expensive to hire.
Building an SRE team can also take time.
Companies may need to change how their development and operations teams work together.
Bad SLOs can make teams focus on the wrong goals.
Too many alerts can cause alert fatigue.
On-call work can also be stressful, especially when engineers receive many unnecessary alerts.
Automation can cause serious problems if it is poorly designed.
Small businesses may not need a full SRE team. They may only need a few SRE practices that solve their main reliability problems.
SRE Security and Reliability
Security and reliability are closely related.
A cyberattack can make a service unavailable, damage information, or stop users from accessing an application.
SRE teams may help manage access controls, encryption, backups, network security, certificates, and cloud settings.
Passwords, API keys, and other sensitive information should be stored securely.
Backups can help recover data after failures or some security incidents.
SRE teams can also work with cybersecurity teams to keep systems safe and reliable.
SRE Best Practices
Good SRE starts with understanding what users need.
Teams should choose useful SLIs and realistic SLOs.
They should automate repeated manual work when automation provides a real benefit.
Monitoring should focus on useful information. Alerts should mainly be sent when someone needs to take action.
Runbooks should be simple and kept up to date.
On-call schedules should be fair and manageable.
Teams should review serious incidents and learn from them instead of blaming people.
Infrastructure as Code can make system management easier.
Teams should also use safe software release methods such as testing, canary releases, feature flags, and rollback plans.
Backups and disaster recovery plans should be tested regularly.
Teams should also check system capacity before a lack of resources causes problems.
SRE is an ongoing process. Teams need to keep improving as systems and user needs change.
In-House SRE vs Outsourced SRE Services
A company can hire its own SRE team or use outside SRE experts.
An in-house SRE can learn the company’s systems and business needs in detail. They can also work closely with other internal teams.
However, experienced SREs may be expensive and difficult to hire.
Outsourced SRE services give companies access to outside experts without hiring full-time employees.
Outside teams can also be increased or reduced depending on how much work is needed.
However, outside engineers may not understand the company’s systems as well as internal employees.
Companies should clearly explain responsibilities, access rules, goals, and reliability targets.
Some companies use both internal and outside SRE experts.
Who Should Consider Site Reliability Engineering?
SRE can be useful for businesses that depend heavily on reliable software.
This can include SaaS companies, cloud services, online platforms, and high-traffic websites.
SRE may also help companies that have frequent outages, growing infrastructure, many microservices, or frequent software updates.
It can also help when engineers spend too much time doing repeated manual work.
Small businesses can use SRE practices without hiring a full SRE team.
For example, they can improve monitoring, automate deployments, use Infrastructure as Code, and review important incidents.
How to Become a Site Reliability Engineer
There is no single way to become an SRE.
Many SREs start in software development, system administration, cloud engineering, DevOps, or other IT roles.
Start by learning Linux and basic operating system skills.
Learn networking topics such as TCP/IP, DNS, HTTP, ports, firewalls, and load balancing.
Learn a programming language such as Python or Go. Shell scripting is also useful.
Learn Git, testing, and debugging.
You should also learn a cloud platform such as AWS, Azure, or Google Cloud.
Learn Docker and Kubernetes if they are useful for the jobs you want.
Study Infrastructure as Code tools such as Terraform.
Learn how monitoring, logs, dashboards, and alerts work.
You should also understand CI/CD, databases, backups, scaling, and incident response.
Learn important SRE terms such as SLI, SLO, SLA, error budget, and toil.
Practical experience is very important. You can build a small cloud application, add monitoring, create alerts, and practice fixing failures.
Certifications can help with learning, but they are not always required. Real experience with systems, coding, and troubleshooting is very valuable.
The Future of Site Reliability Engineering
SRE is changing as software systems become larger and more automated.
Artificial intelligence may help SRE teams study monitoring data, find unusual activity, and understand incidents.
Automated systems may also become better at fixing simple problems without human help.
However, automated recovery needs careful control because a wrong action can create more problems.
Teams may also use past data to predict how many computing resources they will need.
Cloud services and Kubernetes are likely to remain important for many SRE teams.
Managing cloud costs is also becoming more important. Companies need to balance reliability, performance, and cost.
The tools may change over time, but the main goal of SRE will remain the same: keep software services reliable while allowing companies to continue improving them.
Bottom Line
A Site Reliability Engineer helps keep software systems stable, fast, and reliable.
SRE combines software engineering with IT operations. The work can include monitoring, automation, cloud systems, incident response, capacity planning, and software deployment.
SRE also uses SLIs, SLOs, and error budgets to measure reliability.
Not every company needs a full SRE team. However, many businesses can use SRE practices to reduce manual work, prevent problems, and provide more reliable services.
Frequently Asked Questions
What is a Site Reliability Engineer?
A Site Reliability Engineer (SRE) helps keep websites, apps, and computer systems working smoothly and reliably.
What does a Site Reliability Engineer do?
An SRE monitors systems, fixes problems, automates tasks, and helps prevent future system failures.
Is SRE the same as DevOps?
No. DevOps focuses on development and operations working together, while SRE mainly focuses on keeping systems reliable.
What skills does a Site Reliability Engineer need?
An SRE needs skills in coding, Linux, networking, cloud services, monitoring, automation, and problem-solving.
Does an SRE need to know coding?
Yes. Most SREs use coding or scripting to automate tasks, build tools, and solve system problems.
What are SLOs and error budgets?
An SLO is a reliability goal for a service. An error budget shows how much failure is allowed while still meeting that goal.
What tools do SREs use?
SREs may use tools such as AWS, Azure, Docker, Kubernetes, Terraform, Prometheus, Grafana, Git, and Jenkins.
Is Site Reliability Engineering a good career?
Yes, it can be a good career for people interested in coding, cloud systems, automation, and solving technical problems.
More To Explore: